Updated October 13, 2026 (original launch research: August 28). Qwen3.8-Flash is Alibaba’s new hosted multimodal “Flash” model, exposed in Model Studio as qwen3.8-flash. It accepts text, images, and video, returns text, and offers a one-million-token context window. 12 The part most launch summaries miss is the naming: Qwen3.8-Flash and Qwen3.8-Flash-Next are related but not interchangeable products. Flash-Next is the open-weight architecture preview pointing toward Qwen4; the hosted Flash endpoint is the production service. 345167
Key specifications
Alibaba documents up to 991,808 input tokens, 131,072 output tokens, and 1,000,000 total context for hosted Qwen3.8-Flash. 1 Thinking is enabled by default. 8 Function calling, structured output, prefix continuation, and context caching are supported. 129
The current original invocation price in Beijing and Frankfurt is CNY 0.8 per million input tokens and CNY 2.7 per million output tokens. Singapore is CNY 1.094/3.427. US buyer note: Alibaba also lists two Virginia deployment scopes: Global is CNY 0.8/2.7, while the US scope is CNY 1.094/3.427 per million input/output tokens. Do not infer the US-scope rate or data-processing terms from a third-party provider’s advertised USD price. QwenCloud and OpenRouter currently expose a public USD reference around $0.16/M input and $0.47/M output. 171011
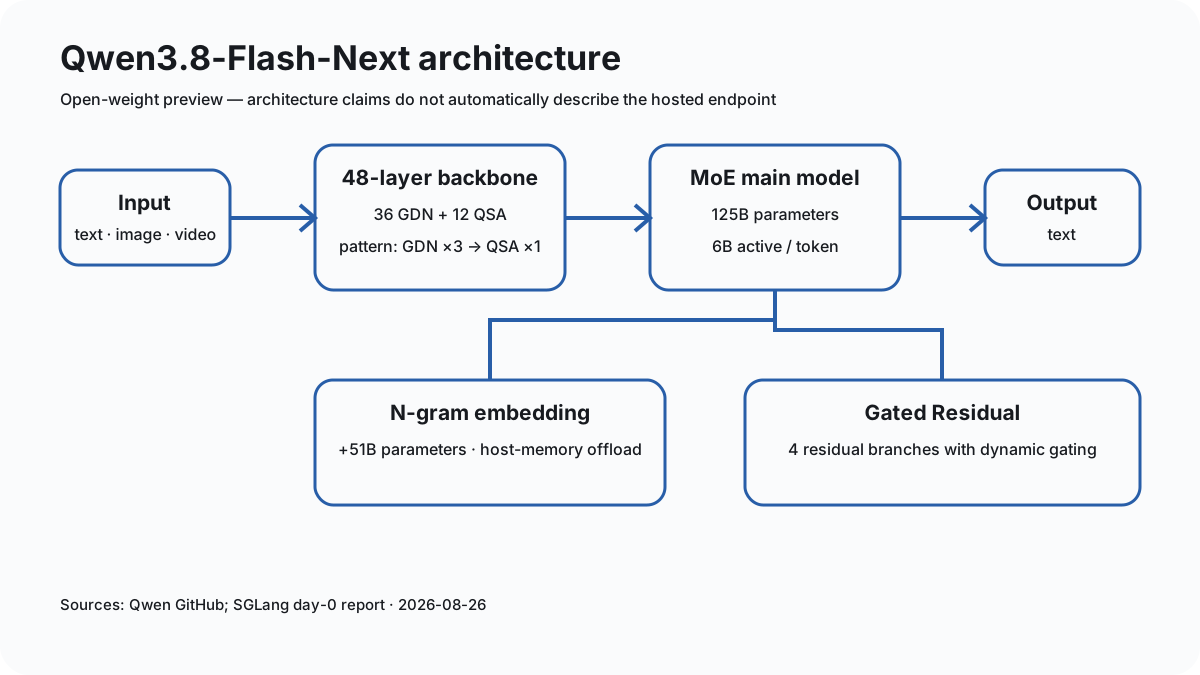
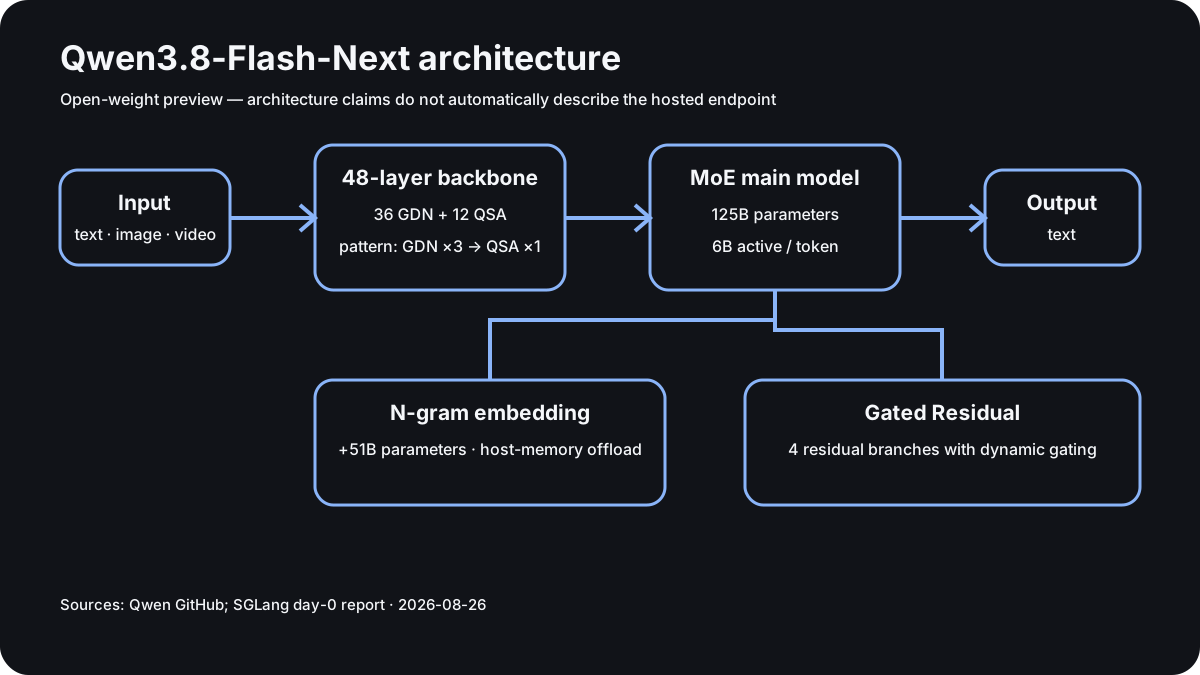
Flash-Next is the model whose architecture has been published: a 125B-parameter main network plus 51B of N-gram embeddings, with 6B parameters active per token. It uses the Qwen Community License 1.0, not Apache-2.0. 412
One launch, two names, two different decisions
On August 26, Alibaba released the production Qwen3.8-Flash service and opened Qwen3.8-Flash-Next weights. Qwen calls Flash-Next an early preview of the architecture intended for Qwen4. 346
That distinction changes what can safely be claimed. The 125B-main-model figure is explicitly documented for Flash-Next. Alibaba’s hosted qwen3.8-flash page does not present that architecture number as a cloud-service specification. Likewise, the Community License applies to the open weights, while hosted API usage is governed by service terms.
| Question | Hosted Qwen3.8-Flash | Qwen3.8-Flash-Next |
|---|---|---|
| What is it? | Production API model | Open-weight architecture preview |
| Identifier | qwen3.8-flash | Qwen/Qwen3.8-Flash-Next on HF |
| Context | 1M tokens | 262K native; Qwen describes YaRN extension to 1M |
| Local weights | Not implied by hosted model ID | Yes |
| Published architecture | Cloud page focuses on capabilities/limits | 125B main + 51B N-gram, 6B active/token |
| License | Hosted service terms | Qwen Community License 1.0 |
A genuinely large context window
For the hosted model, Alibaba lists 1,000,000 tokens of context, with a 991,808-token maximum input in non-thinking mode or 983,616 in thinking mode. Output can reach 131,072 tokens, and the maximum thinking-chain length is 262,144. 1
A million-token limit is useful for repository-scale code analysis, long document collections, persistent agent traces, and video-plus-text workloads. It should not be read as a recommendation to fill the window on every request: long prompts still affect latency, spend, retrieval precision, and failure modes.


Pricing changed almost immediately after launch reporting
Reuters’ August 26 report quoted the launch price at CNY 1/M input and CNY 3/M output. Alibaba’s live Model Studio documentation checked on August 28 already lists CNY 0.8/2.7 for Beijing and Frankfurt. Singapore is CNY 1.094/3.427. 1713
For a fast-moving API, the current regional pricing page should therefore override a launch-day news article when the two disagree. For the larger model, the separate Qwen3.8-Max pricing and benchmark guide keeps that comparison distinct.
Qwen3.8-Flash is not cheaper than 3.7 at every prompt length
The comparison becomes more interesting against Qwen3.7-Flash. Alibaba’s Qwen3.7-Flash model page lists CNY 0.2/M input and CNY 0.8/M output for requests up to 32K in Frankfurt/Global scope and Beijing (standard list rates rechecked October 13, 2026). Against Qwen3.8-Flash’s flat CNY 0.8/2.7, the newer model is 4× more expensive on short input and 3.375× on output.
At 256K–1M, however, qwen3.7-flash moves to CNY 1.2/4.8. Qwen3.8-Flash is then 33.3% cheaper on input and 43.75% cheaper on output. 7
That makes the economics workload-dependent. A short classification service may still favor Qwen3.7-Flash on pure token cost; long-context coding and agent workloads have a much stronger cost case for 3.8.


Monthly API cost examples
Using the currently listed $0.16/M input and $0.47/M output public API reference: 1011
- Light: 10M input + 2M output = $2.54/month
- Medium: 100M input + 20M output = $25.40/month
- Heavy: 1B input + 200M output = $254/month
These are transparent token-only calculations: (input millions × $0.16) + (output millions × $0.47). Search, storage, provider routing, caching behavior, taxes, and future price changes can alter the bill.
Why Flash-Next is architecturally interesting
Flash-Next combines Gated DeltaNet (GDN) with Qwen Sparse Attention (QSA). SGLang’s day-zero engineering report describes a 48-layer model: 36 GDN layers and 12 QSA layers, arranged as three GDN layers followed by one QSA layer. The sparse-attention path indexes compressed micro-blocks and retrieves a bounded set of relevant positions rather than attending densely over the full sequence. 414
The model also adds Gated Residual, which expands the residual stream into four branches, and a large N-gram Embedding memory. Qwen lists 51B N-gram embedding parameters on top of a 125B main model, while only 6B parameters are active per token. SGLang shows how that embedding table can be kept in host memory and asynchronously prefetched, reducing permanent GPU-weight pressure. 414
Qwen says training cost was about one ninth of Qwen3.7-Plus while delivering stronger coding and office-task capability. Treat that as a vendor efficiency claim; the public sources reviewed here do not provide an independent reconstruction of Alibaba’s training bill. 413
Benchmarks: useful evidence, not a single truth score
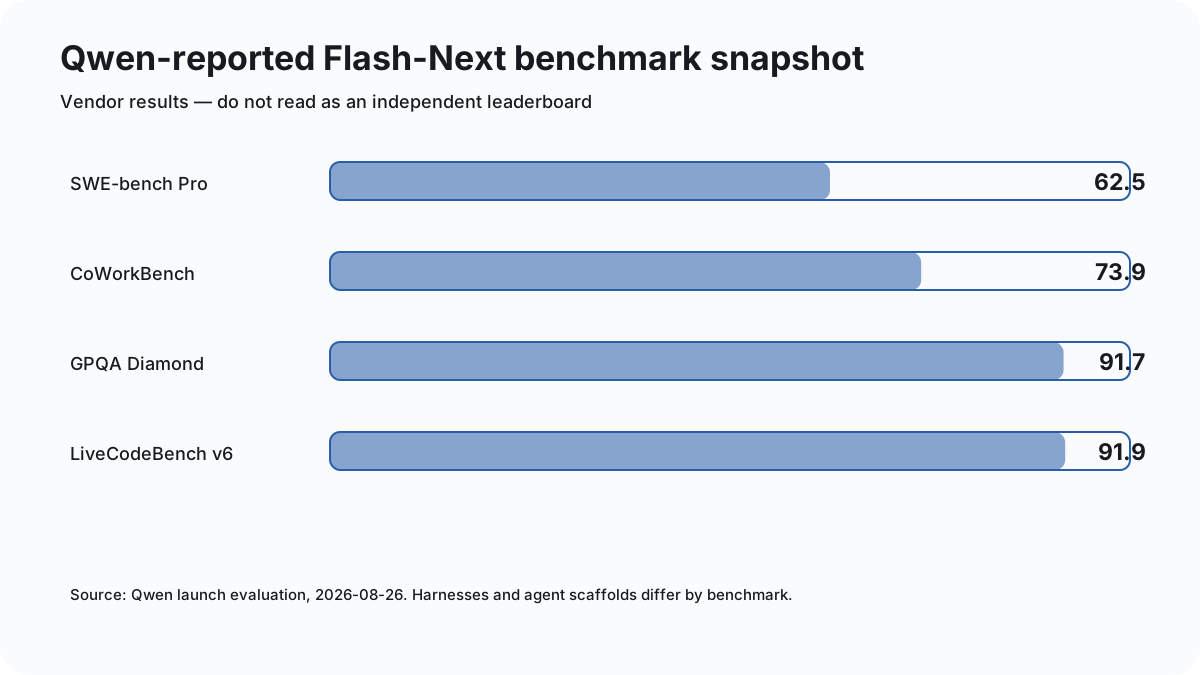
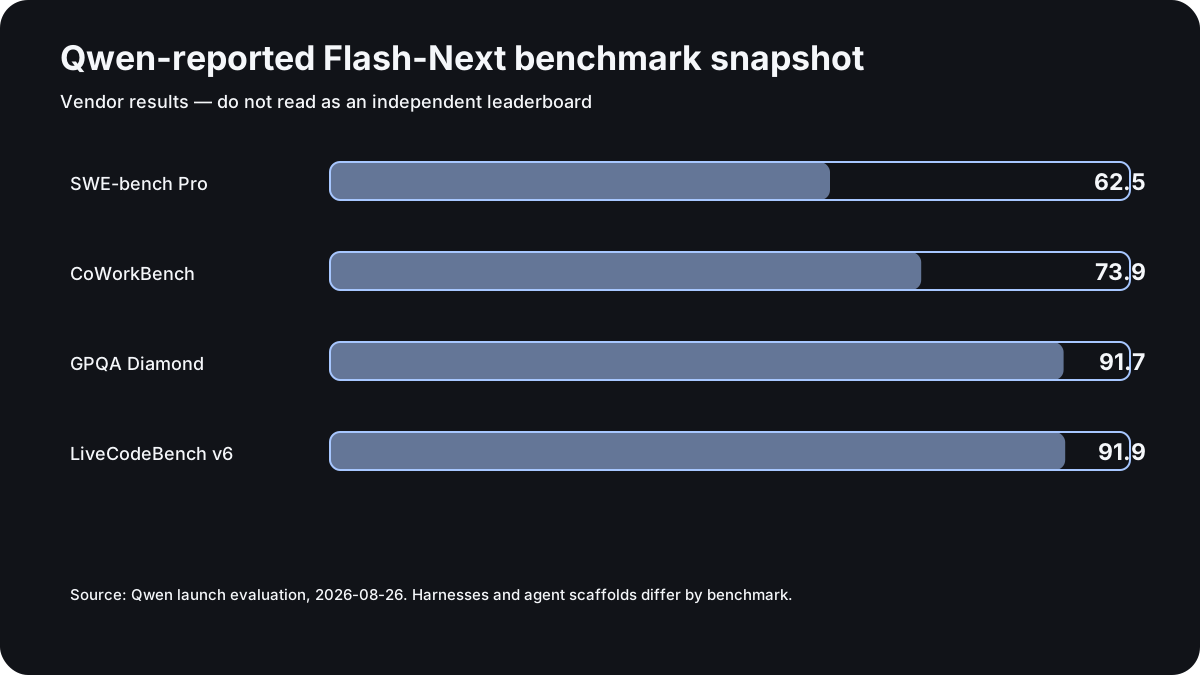
Qwen reports 62.5 on SWE-bench Pro, 81.0 on SWE-bench Multilingual, 73.9 on CoWorkBench, 91.7 on GPQA Diamond, and 91.9 on LiveCodeBench v6 for Flash-Next. These are strong vendor-reported results, but harness choice, agent scaffolding, sampling, and tool configuration matter. 3
Artificial Analysis offers a different kind of evidence. At retrieval time it gives Flash-Next an Intelligence Index of 56 and reports roughly 73.4 output tokens/s with a 2.98-second time to first token on the tested Alibaba endpoint. 15
The two sets should stay separate: Qwen’s task benchmarks describe capability under its evaluation setups, while Artificial Analysis measures its own standardized index and serving characteristics.
Hosted API features and regional differences
Alibaba supports OpenAI-compatible Chat Completions and Responses APIs and an Anthropic-compatible Messages API. The model supports tools/function calling and structured outputs; thinking is enabled by default. 161781819
The deployment region affects more than data location. Frankfurt supports context caching but, according to the current model page, not the built-in web-search feature for Qwen3.8-Flash. Beijing supports batch inference, while Singapore and Frankfurt do not for this model; Alibaba’s batch docs also cap a batch request at 256K context. 12021
Rate limits differ too: Alibaba currently lists 30,000 RPM/5M TPM for Beijing, 15,000 RPM/2M TPM for Singapore, and 30,000 RPM/5M TPM for Frankfurt. 22
Frankfurt infrastructure is not the same as EU scope
Alibaba’s official model-by-region context-cache list includes qwen3.8-flash in Frankfurt’s “Global scope”, but does not list it under Frankfurt’s separate “EU scope” as rechecked October 13, 2026. The individual model page explicitly labels its Frankfurt deployment Global scope, which is a different contractual distinction from EU scope. A Frankfurt hostname, data-center location or available Global-scope model does not demonstrate contractual EU-scope processing. For personal or client data, verify access within the specific EU deployment scope, applicable DPA, retention and onward transfers. Do not silently fall back to Global if the intended EU-scoped model is unavailable. USD billing is not evidence of U.S. residency either.
Prompt caching saves compute; it does not automatically increase plan quotas
Alibaba documents two distinct context-cache mechanisms:
| Property | Implicit (automatic) cache | Explicit cache |
|---|---|---|
| Activation | Automatic, cannot currently be disabled | Mark eligible blocks with cache_control: {"type":"ephemeral"} |
| Hit reliability | Common-prefix reuse, not guaranteed | Explicit marked prefix reusable after its cache is created |
| Minimum size | 1,024 tokens for a possible hit | 1,024 tokens per block |
| Qwen3.8-Flash, Frankfurt/Global | Cache read CNY 0.1 / 1M tokens (12.5% of regular input) | Creation CNY 1.25 / 1M (156.25%); cache read CNY 0.1 / 1M (12.5%) |
| Retention | Undetermined, periodically purged | Five minutes, renewed on a hit |
Standard baseline versus model rates: Alibaba’s general context-caching baseline lists explicit cache creation at 125% and hits at 10% (with implicit cache hits at 20% of the standard input rate). Why the previous 20% figure was wrong for this model: Alibaba explicitly excludes qwen3.8-flash from its general implicit-cache discount rule. The Qwen3.8-Flash model price sheet lists ordinary input at CNY 0.8/M, cache hits at CNY 0.1/M (both implicit and explicit), and explicit cache creation at CNY 1.25/M for Frankfurt/Global scope. These translate to 12.5% and 156.25% of ordinary input, respectively. Singapore and other deployment scopes can have different rates. Explicit caching still requires eligibility for the exact model/region/scope, and the separate Responses API session cache is not interchangeable with Chat Completions caching.
Illustration, not a measured bill: If 10M input tokens all count as cache hits under the Frankfurt/Global tariff, those reads cost CNY 1.00 versus CNY 8.00 for 10M ordinary input tokens. This excludes cache creation, cache misses, regular input, generated output and any other fees. Confirm actual billed cached tokens in the response usage fields and provider invoice before applying the discount to your workload. A high cache-hit rate does not imply a matching increase in a subscription’s weekly credits. For a long-running coding agent, track actual billed input, cached tokens, rate-limit errors, reset windows and remaining plan quota in the provider dashboard separately. Our editorial team executed no billable API calls for this analysis.
Local use: technically supported, not a small-model experience
For local inference, look at Flash-Next rather than the cloud model name. Qwen lists Transformers, llama.cpp, MLX/mlx-vlm, SGLang, vLLM, and other routes. Apple Silicon support is explicitly mentioned through MLX for text and vision. 4 If you want to start with a smaller local checkpoint, the Qwen3.8 27B guide is a more realistic baseline.
Memory is the hard constraint. Unsloth says its extreme 1-bit Dynamic GGUF can run with about 75GB of RAM or unified memory. That is a third-party quantization claim, not an official minimum, but it illustrates the scale: a 16GB or 32GB Mac is not a realistic target for the currently advertised full-model local variants. 2324 The unified-memory guide explains the memory-budgeting problem in more general terms.
Local runtime limitations: version matters
The original August 28 report captured specific development issues, including speculative-decoding N-gram cache state and a QSA/SSM accelerator path. Those reports were valuable at launch but must not be generalized as confirmed defects in today’s releases. Recheck the exact issue status and your serving version before claiming a regression.25262728
Qwen’s official Flash-Next model card now lists a 180B-parameter repository, an experimental qwen4_exp architecture, and the Qwen Community License 1.0. This does not make hosted qwen3.8-flash a downloadable checkpoint: the service and its open-weight architectural relative are separate offerings. The full original repository is approximately 360GB of files; that is not an optimized Mac download, quantized running-memory measurement or an assertion that every 180B parameter is active in each token.
For a controlled local experiment, capture: checkpoint revision, quantization, actual runtime/driver versions, 4K/32K context, vision input handling and any enabled tool parser. Compare the result with a smaller Qwen3.8-27B checkpoint on the same Mac. Without a repeatable measurement, leave performance and cross-model quality claims open.
The license deserves a real read
The Flash-Next weights use Qwen Community License 1.0. It broadly grants rights to use, copy, modify, distribute, sell, deploy, host, fine-tune, and create derivatives, subject to conditions. The license adds attribution requirements at very large commercial scale and requires a separate license for certain Model-as-a-Service and AI Work Assistant commercial uses. 12
For commercial deployment, check the license text against your exact product. Calling the release simply “Apache-style open source” would be inaccurate.
An evidence-based cloud-versus-Mac comparison
Before choosing a service, define three actual tasks: structured extraction with a fixed JSON schema, a small code fix checked by executable tests, and a long document task with pre-defined pass/fail criteria. Record exact model IDs, API region, context size, input/output tokens, total charges, and accepted outcomes. The qwen3.8-flash cloud endpoint is not the Qwen3.8-Flash-Next open-weight checkpoint.
For local runs, also capture the Mac chip, unified memory, quantization, runtime version, and memory pressure in Activity Monitor → Memory. Record swap usage under the same workload, not only the model file size. Flash-Next carries the Qwen Community License 1.0, not Apache 2.0; review the actual license conditions before commercial deployment. The storage calculations and community reports cited here are not original Mac performance measurements performed by AI on Mac.
Deployment decision (October 2026)
API decision: For hosted use, check QwenCloud’s current model page for the correct regional price, tool availability, API key scope and rate limit before ordering capacity. The CNY tier diagram reflects list rates rechecked October 13 for Frankfurt/Global scope and Beijing, not a contractual quote, cache price chart or a statement of EU-scope availability. For offline use, check the Qwen/Qwen3.8-Flash-Next weights and license separately.
Qwen3.8-Flash is compelling when the workload combines long context, multimodal inputs, tool use, and low API pricing. It is not automatically the cheapest choice for short prompts; Qwen3.7-Flash can still cost materially less in the lowest context tier.
Flash-Next is a separate proposition: it is the more interesting release for architecture research, self-hosting, quantization, and Qwen4 experimentation, but it requires much more memory and a local serving ecosystem that is still stabilizing days after release.
The practical decision is therefore simple: choose hosted Qwen3.8-Flash for production API economics and long context; evaluate Flash-Next when control over weights and local inference matters enough to justify the hardware and integration cost.
Methodology
Original research: August 28, 2026; model-card and runtime-language update: October 8, 2026. The source register contains 37 links, with first-party Alibaba/Qwen documentation prioritized for identity, limits, pricing, compatibility, and licensing; independent benchmark and implementation sources were used to test or qualify vendor claims. Pricing and deployment status are time-sensitive.
Sources and evidence
Model, API and license claims are linked to their originating sources. Community or vendor benchmarks are not independent Apple Silicon measurements.
Footnotes
Frequently Asked Questions
How much does Qwen3.8-Flash cost?
Alibaba lists CNY 0.8 per 1M input tokens and CNY 2.7 per 1M output tokens in Frankfurt and Beijing. Singapore is CNY 1.094/3.427; public USD references are around $0.16/$0.47.
What's the difference between Qwen3.8-Flash and Flash-Next?
Qwen3.8-Flash is the hosted production endpoint. Qwen3.8-Flash-Next is an open-weight architecture preview; the 125B main model, 51B N-gram embedding, and 6B active-per-token figures belong to Flash-Next.
How large is the Qwen3.8-Flash context window?
The hosted model has 1,000,000 total context tokens, up to 991,808 input tokens in non-thinking mode, and 131,072 output tokens. Thinking mode lowers the maximum input to 983,616 tokens.
Is Qwen3.8-Flash cheaper than Qwen3.7-Flash?
Not for short prompts: up to 32K, Qwen3.8-Flash is four times more expensive on input. In the 256K–1M tier it is about 33.3% cheaper on input and 43.75% cheaper on output.
Can Qwen3.8-Flash run locally on a Mac?
The hosted endpoint is not a local model. Flash-Next is the relevant route for local tests; one concrete 1-bit quantization is described at about 75GB of RAM or unified memory. A 16GB or 32GB Mac is not a realistic target.
Is Qwen3.8-Flash-Next open source?
The weights are openly available under the Qwen Community License 1.0, not Apache-2.0. The license requires separate review or licensing for certain commercial Model-as-a-Service and AI Work Assistant businesses.