Updated October 9, 2026. Benchmark figures below are historical August launch claims; provider pricing and completion limits were checked against current listings. Tencent released Hy4 preview on August 28 and published the model weights. Its headline specification is unusually large for an openly available model. The backbone has 770B parameters, with 49B active per token. It advertises a 1M-token context window. Tencent Cloud’s API documentation is more precise: 1024k context, 960k maximum input and 64k maximum output. 123
The benchmark caveat is central: most of the eye-catching launch benchmarks are still vendor-reported Tencent results. They are useful evidence, but they are not yet independent replications. Tencent also labels Hy4 as an early release and openly lists over-long reasoning and excessive self-verification among its known limitations. 2
Architecture and deployment limits
- Release: August 28, 2026
- Architecture: 770B total / 49B active MoE
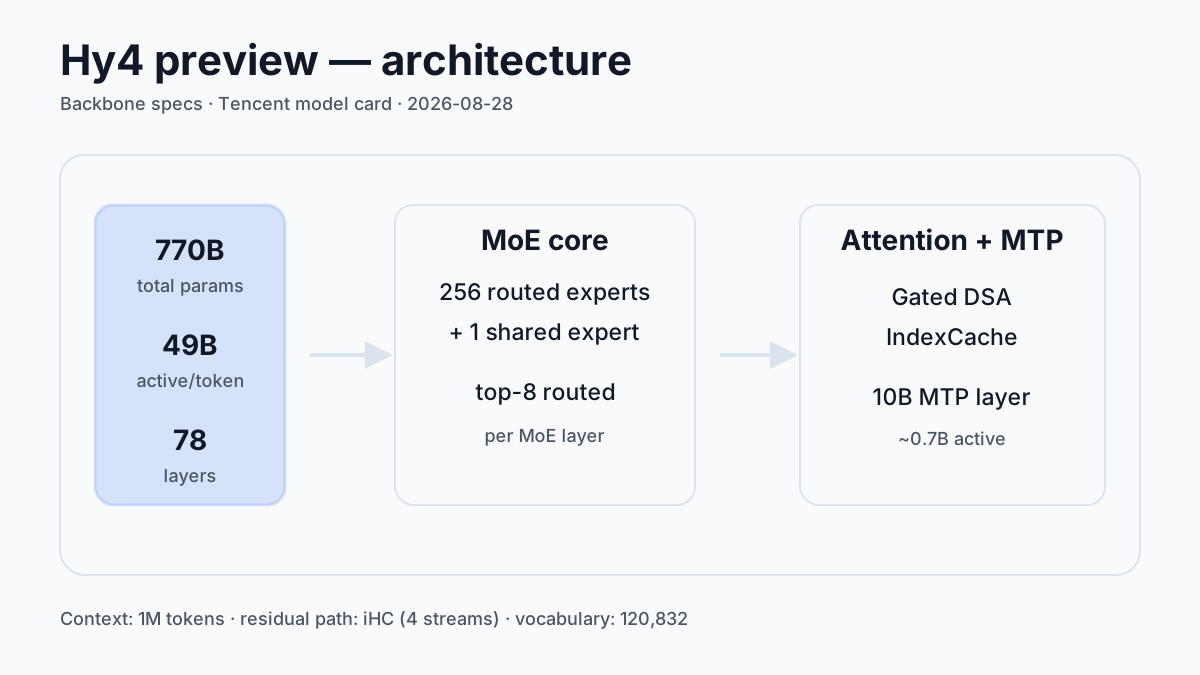
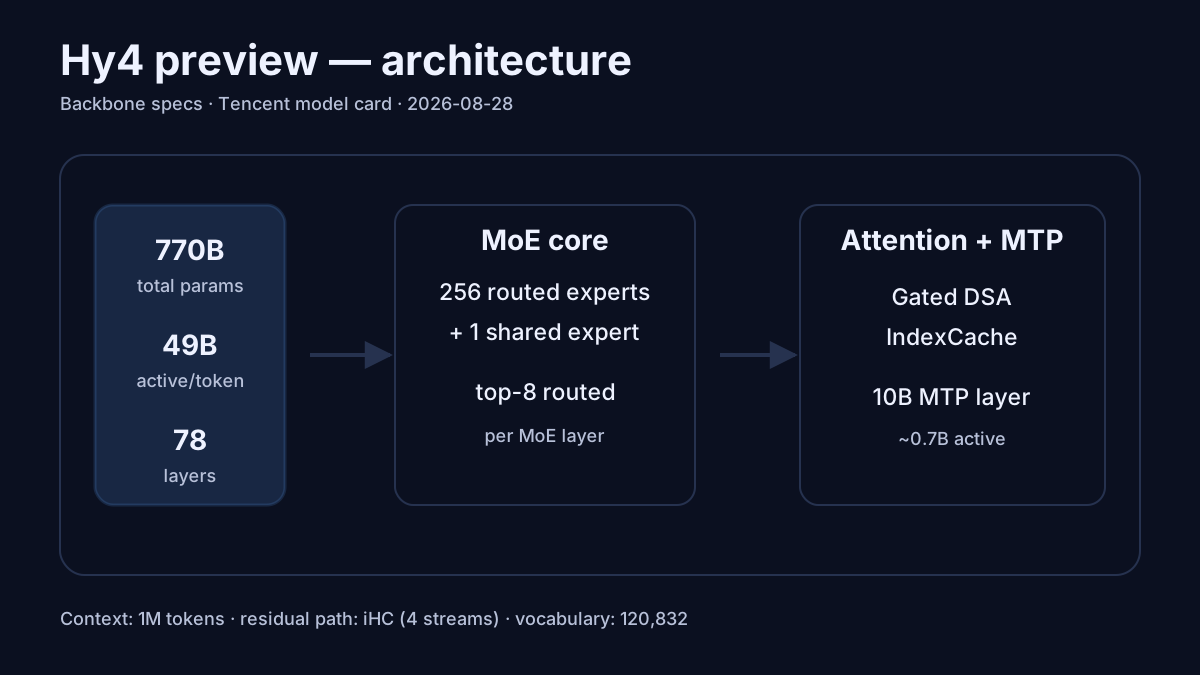
- Backbone: 78 layers; 256 routed experts + 1 shared expert in each MoE layer; top-8 routed experts active
- Native MTP: 10B total / about 0.7B active
- Context: 1M model context; Tencent Cloud exposes 1024k / 960k max input / 64k max output
- License: Apache 2.0
- APIs: Tencent Cloud TokenHub and OpenRouter
- OpenRouter list price: $0.834/M input, $2.501/M output, $0.042/M cache read
- Tencent Cloud list price shown for Guangzhou: 6 / 18 / 0.3 CNY per M tokens for input / output / cache hit
- Self-hosting: possible, but official serving guidance is firmly in multi-GPU datacenter territory
Architecture: where the 770B number comes from
Hy4 preview is a Mixture-of-Experts model, so “770B parameters” does not mean all 770B participate in every token. Tencent’s backbone uses 78 layers. The first feed-forward block is dense; the remaining 77 are MoE layers with 256 routed experts and one shared expert. Each token selects the top eight routed experts plus the shared expert. The published active-parameter figure is 49B per token. 2
A native Multi-Token Prediction (MTP) layer adds 10B total parameters, roughly 0.7B active. Tencent pairs this with Gated DeepSeek Sparse Attention, IndexCache for cross-layer sparse-index reuse, and an iHC residual pathway with four residual streams. 24
IndexCache has a separate research paper describing cross-layer reuse of sparse-attention indexing. That paper is valuable for understanding the mechanism, but its speedups should not be pasted onto Hy4 as if they were production end-to-end measurements. The experiments and the released service are not the same object. 4
The jump from Hy3 preview
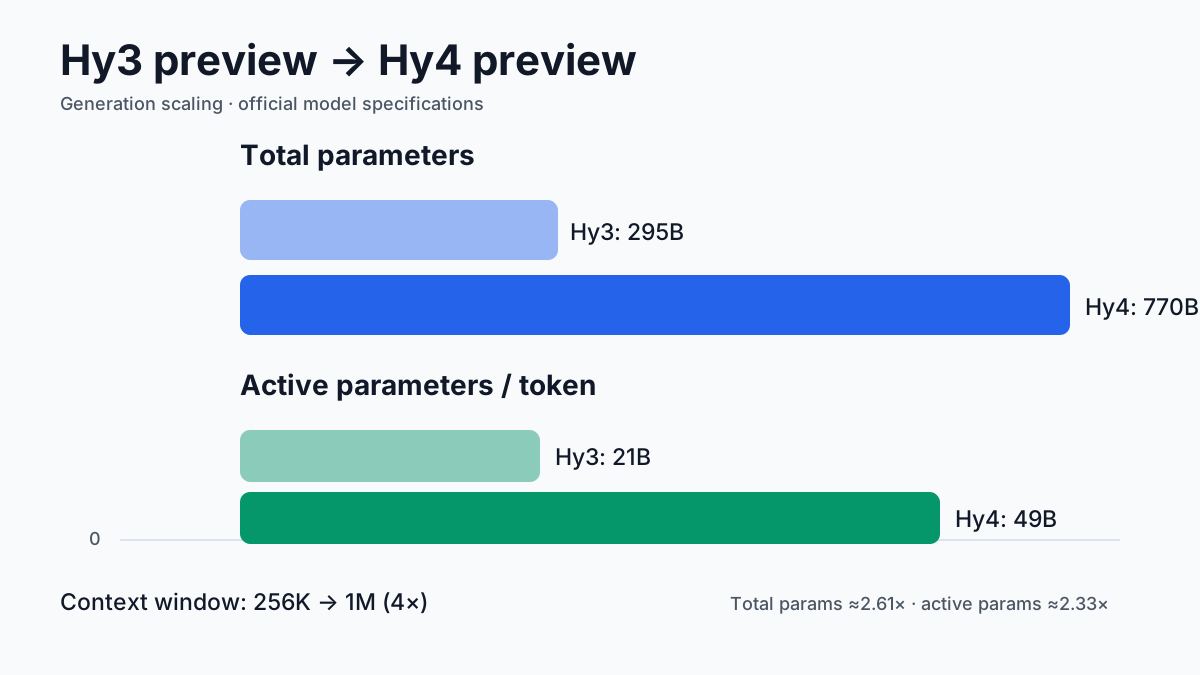
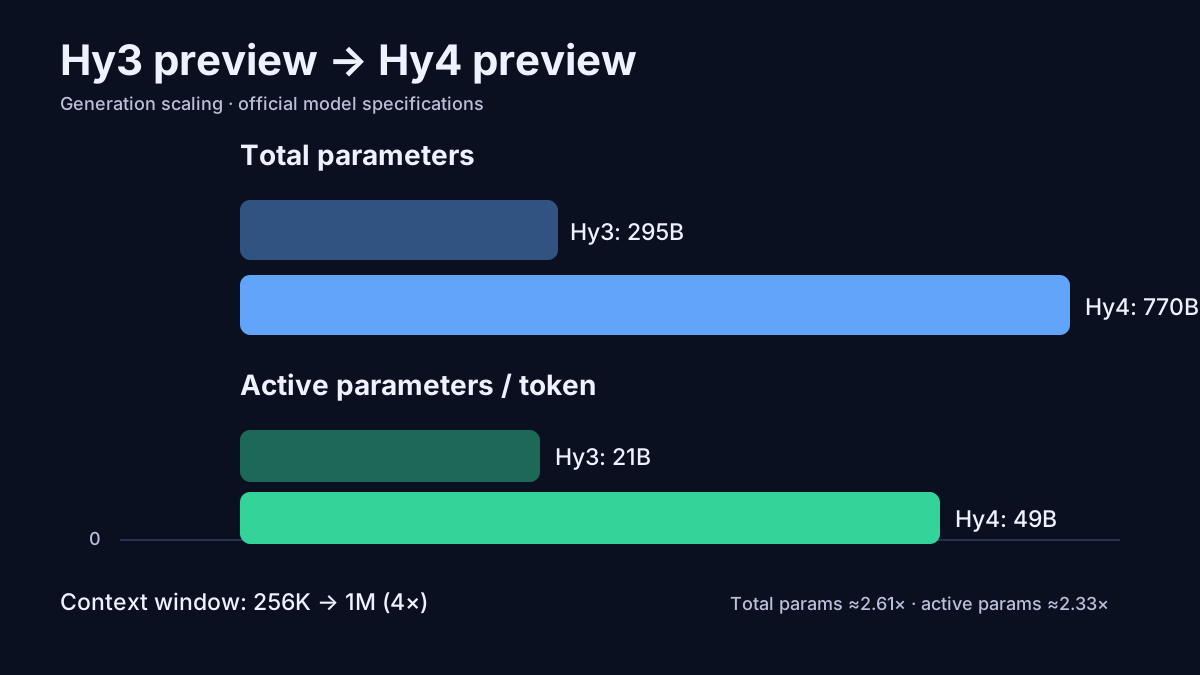
Hy3 preview shipped with 295B total parameters, 21B active parameters and a 256K context window. Hy4 moves those figures to 770B, 49B and 1M. On the raw specifications, that is roughly 2.61× the total parameter count, 2.33× the active parameter count and 4× the nominal context. 52
For the earlier generation and its OpenRouter angle, see Tencent Hy3 on OpenRouter.
Tencent attributes the generational improvement to more than scale: it says pre-training, post-training and training-data volume all increased. There is not enough public ablation data to assign a clean share of the gain to each factor. 12
“1M context” is real, but deployment limits still matter
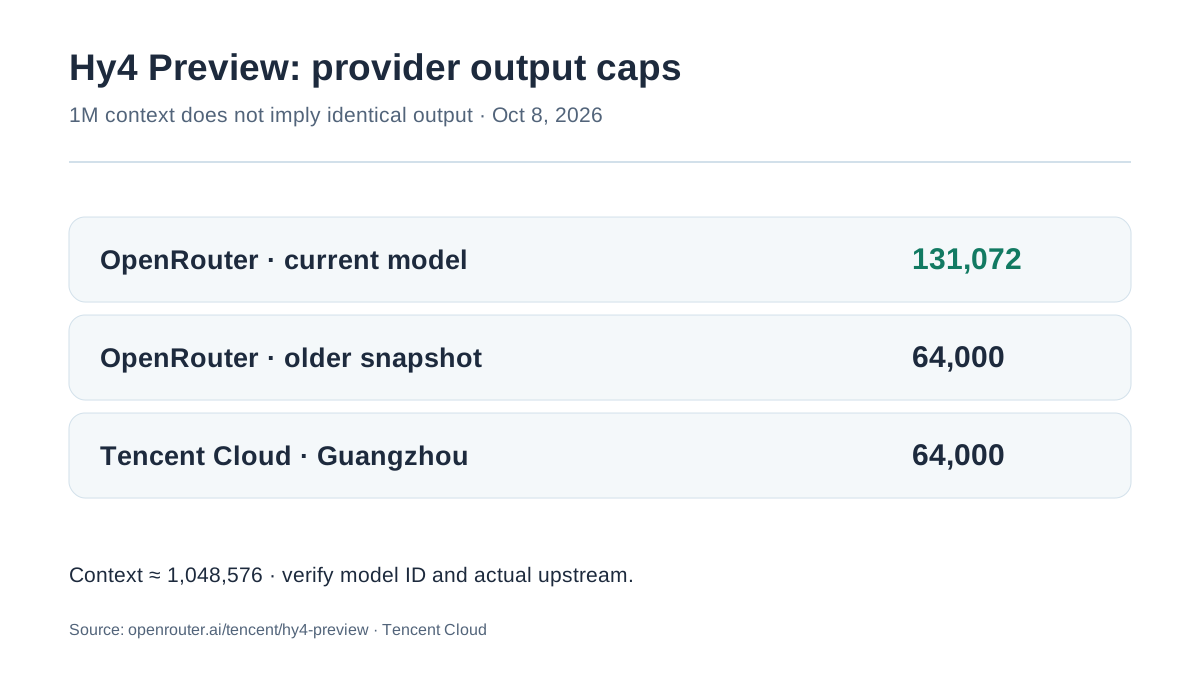
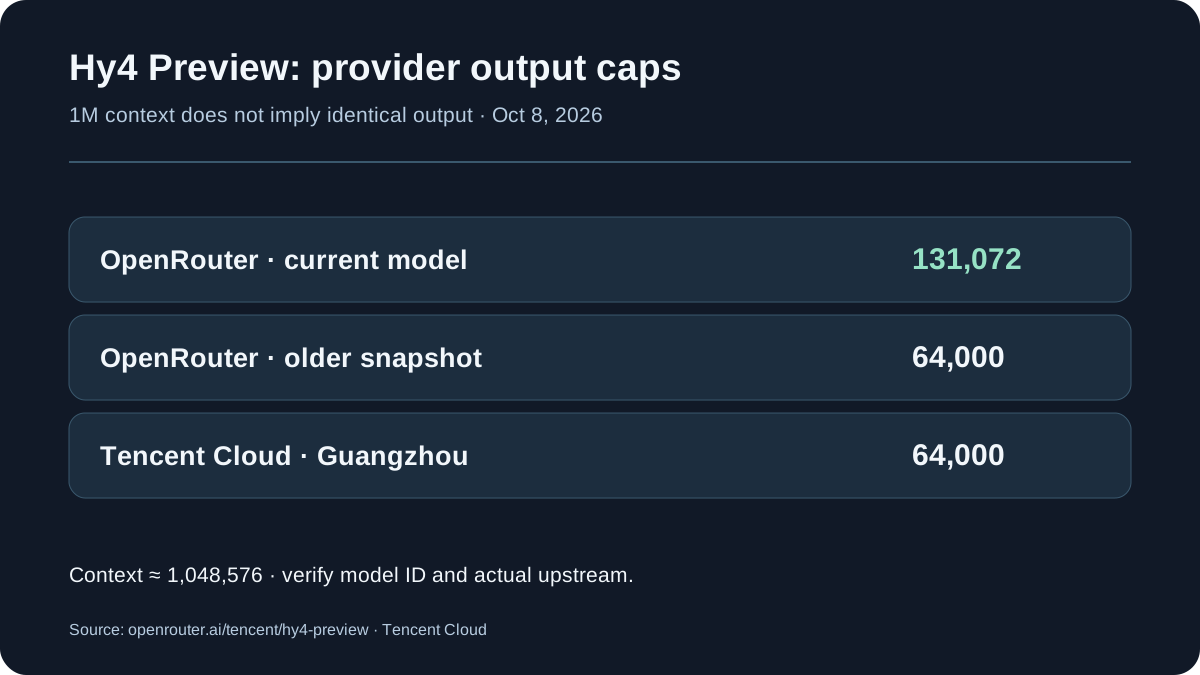
OpenRouter’s current tencent/hy4-preview model listing shows 1,048,576 context tokens and up to 131,072 output tokens. A separate, dated snapshot such as tencent/hy4-preview-20260827 still lists 64,000 output tokens. Tencent Cloud’s own hy4-preview API documents 1024K total context, 960K maximum input and 64K output. Those are different provider/revision ceilings, not proof that one of the vendors’ documentation is inaccurate. Pin the exact route and verify its limits before sending 100K-output jobs. Current OpenRouter · dated revision · Tencent Cloud API.
Those numbers can coexist. Model context is a total budget; a service can cap prompt tokens below the window to preserve room for generation and internal behavior.
Self-hosting introduces another constraint: KV-cache memory. SGLang explicitly recommends sizing the context length to the available KV budget and gives substantially smaller reference settings such as 262K on several GPU configurations. Supporting a 1M maximum does not mean a given server configuration can economically serve 1M at high concurrency. 6
Provider-specific output ceilings and dated snapshots
The 131,072-output allowance on the current OpenRouter listing is not a promise that every upstream route or older snapshot supports it. Verify the actual revision and endpoint metadata; other contexts, such as Tencent Cloud’s 64K output cap, can still be correct. Current OpenRouter · dated snapshot.
API compatibility and agent features
Tencent Cloud states that Hy4 preview is compatible with OpenAI Chat Completions, OpenAI Responses and Anthropic Messages. Its guide includes streaming, reasoning controls, function calling and JSON-schema structured output. Reasoning defaults to high; a direct-response/no-think path is available. 3
OpenRouter separately lists tool calling and JSON-schema structured outputs for its route. 7
Those capabilities make Hy4 a candidate for coding agents and tool-heavy workflows. Compatibility still needs application-level testing: parser conventions, reasoning fields, tool-call edge cases and retry behavior can differ even when the top-level protocol looks familiar.
What Hy4 preview means for Mac users
For a Mac, Hy4 preview is primarily a cloud model or remote server, not a local desktop model. The Mac can still be the useful control plane: it selects files, runs the agent, executes approved shell commands and records costs and failures. Inference happens at the API provider or on a remote multi-GPU host.
| Goal | Practical Mac path | Check before use |
|---|---|---|
| Coding agent over a local repository | API client on the Mac, sending only selected files | privacy, tool permissions, retries and token cost |
| Offline or confidential work | smaller local model through Ollama, MLX or llama.cpp | whether web search, plugins and cloud fallbacks are truly disabled |
| Self-host Hy4 | Mac as development and control machine, serving on remote GPUs | SSH/API security, model version, KV cache and infrastructure cost |
| Test the 1M context | start with a controlled document against the API limit | actual input cap, cache rules, latency and retrieval quality |
The key data path is the prompt, not the weight download: source code, screenshots, terminal output and tool results leave the Mac as soon as the API route is used. A local agent can select and redact that data, but it does not make Hy4 a local model. For a fair comparison, run the same Mac workflow once with a small local fallback and once with Hy4, measuring success rate, total tokens, tool-call errors, elapsed time and cost per completed task.
Pricing: the cache rate is the number to watch
United States: U.S. billing does not mean U.S. inference
For American developers, OpenRouter quotes USD API list prices, with possible state/local sales tax and payment-provider fees depending on the billing entity and location. A U.S. credit card, account or English prompt does not force inference to remain in the United States. OpenRouter lists third-party upstream hosts, including DeepInfra, NovitaAI and SiliconFlow. Check provider filtering, routing, retention policy and a suitable DPA or contract before sending private code or customer data. Tencent Cloud’s displayed CNY price is explicitly tied to Guangzhou, not a quoted U.S. regional service. OpenRouter providers.
U.S. license: Hy4 Preview is Apache 2.0, unlike MiniMax H3
Tencent’s Hy4 Preview weights are published under Apache 2.0, including for U.S. developers who comply with the license. That differs from MiniMax H3, whose separate Community License excludes the United States for the ordinary open-weight grant. These are unrelated licensors and models. License terms do not eliminate the hardware bill: full-scale Hy4 deployment still targets datacenter-class multi-GPU servers. Tencent license.
Checked October 9, 2026: OpenRouter’s standard listing quotes $0.834 fresh input / $2.501 output / $0.042 cached input per million tokens. Tencent Cloud’s documented Guangzhou scope separately quotes 6 CNY input / 18 CNY output / 0.3 CNY cache hit. Those prices have different billers, currencies and upstream conditions. A U.S. billing address does not turn Guangzhou’s CNY tariff into an equivalent U.S. endpoint. OpenRouter · Tencent Cloud.
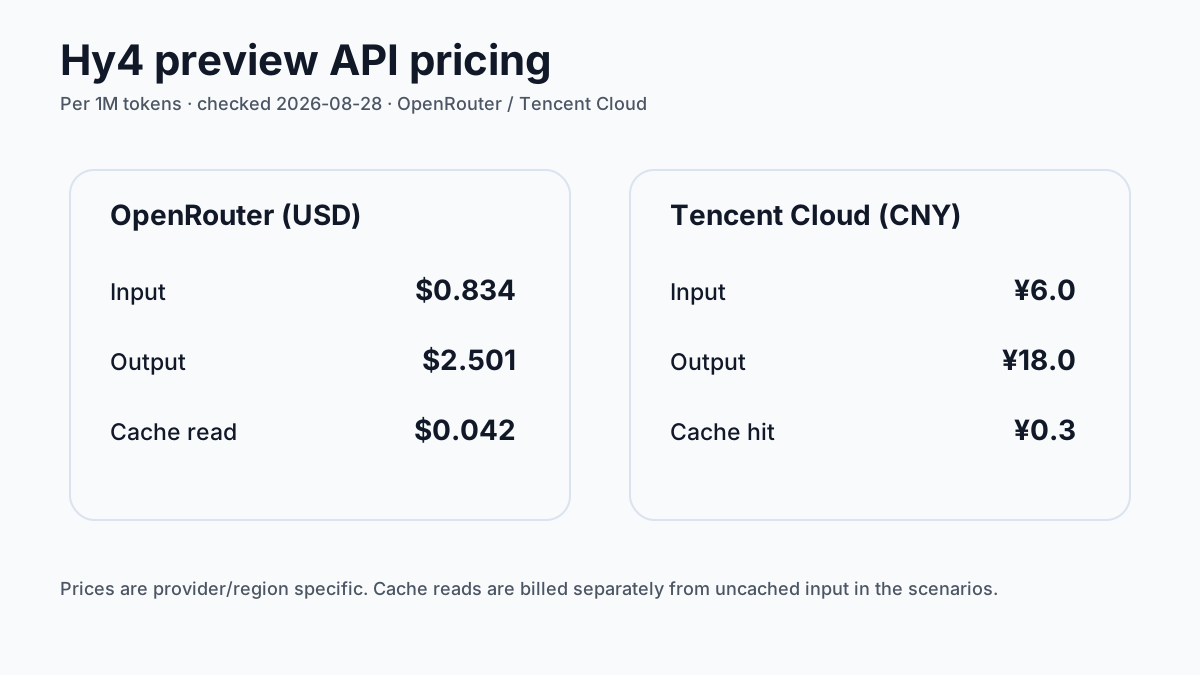
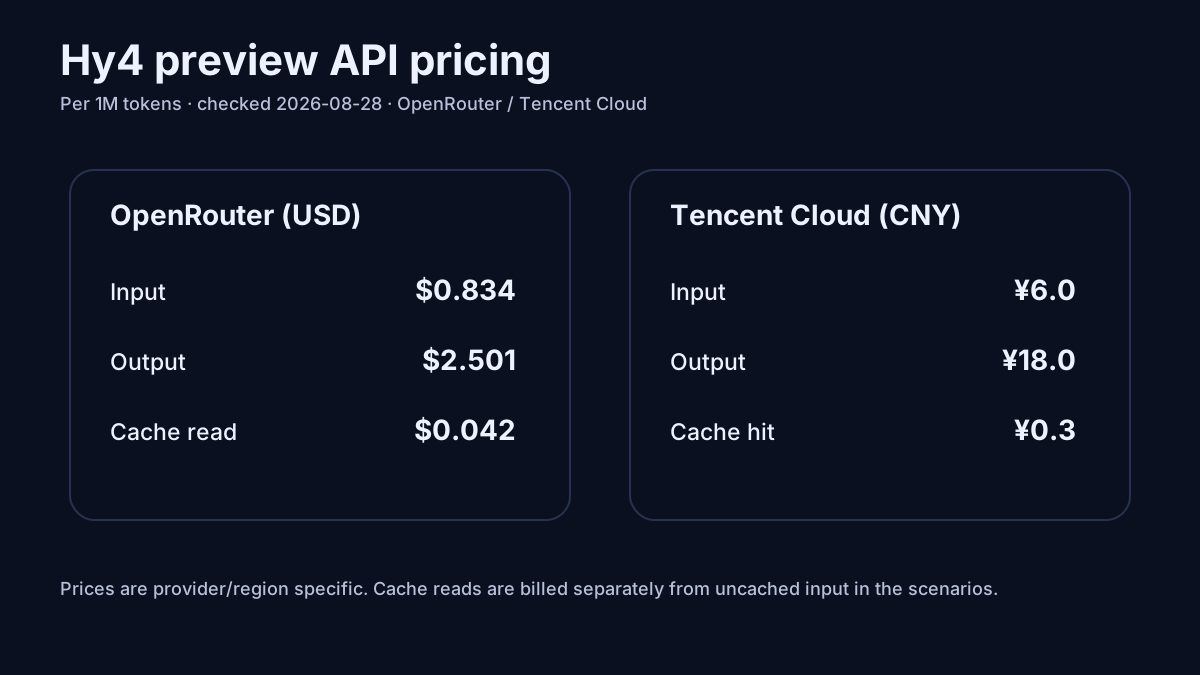
The following scenarios apply the published rates. Uncached input is billed at the input rate, and successful cache reads at the cache-read rate.
OpenRouter cost = input_M × 0.834 + output_M × 2.501 + cache_read_M × 0.042
| Workload | Uncached input | Output | Cache reads | OpenRouter | Tencent Cloud |
|---|---|---|---|---|---|
| Light | 2M | 0.5M | 10M | $3.34 | 24 CNY |
| Medium | 20M | 5M | 100M | $33.39 | 240 CNY |
| Heavy | 200M | 50M | 1,000M | $333.85 | 2,400 CNY |
For document-heavy agents, cache economics can dominate the bill. Do not project these savings until you have verified the target provider’s cache semantics, eligibility and retention behavior.
Benchmark results: impressive, but label them correctly
Tencent’s launch material publishes a broad set of strong scores. Hugging Face’s automated evaluation-metadata discussion, for example, records 65.7 on SWE-Bench Pro and points back to the model card as the source. A same-day analysis transcribes additional Tencent figures including 85.4 on Terminal-Bench 2.1, 82.9 on SWE-bench Multilingual, 64.3 on DeepSWE, 92.3 on GPQA Diamond, 74.1 on Toolathlon-Verified, 83.7 on MCP-Atlas and 55.4 on Humanity’s Last Exam with tools. 12
| Benchmark | Hy4 preview | Evidence status on Aug. 28 |
|---|---|---|
| GPQA Diamond | 92.3 | vendor-reported |
| Terminal-Bench 2.1 | 85.4 | vendor-reported |
| MCP-Atlas | 83.7 | vendor-reported |
| SWE-bench Multilingual | 82.9 | vendor-reported |
| Toolathlon-Verified | 74.1 | vendor-reported |
| SWE-Bench Pro (public) | 65.7 | vendor-reported |
| DeepSWE | 64.3 | vendor-reported |
| HLE with tools | 55.4 | vendor-reported |
| APEX-Agents | 37.1 | vendor-reported |
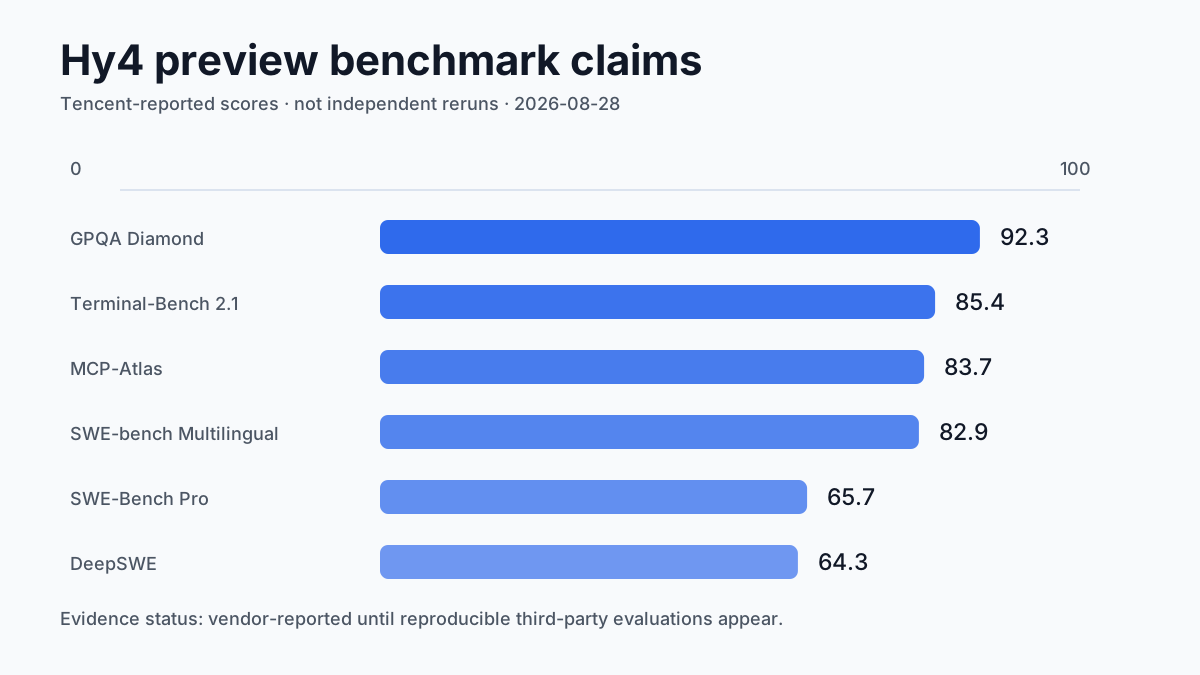
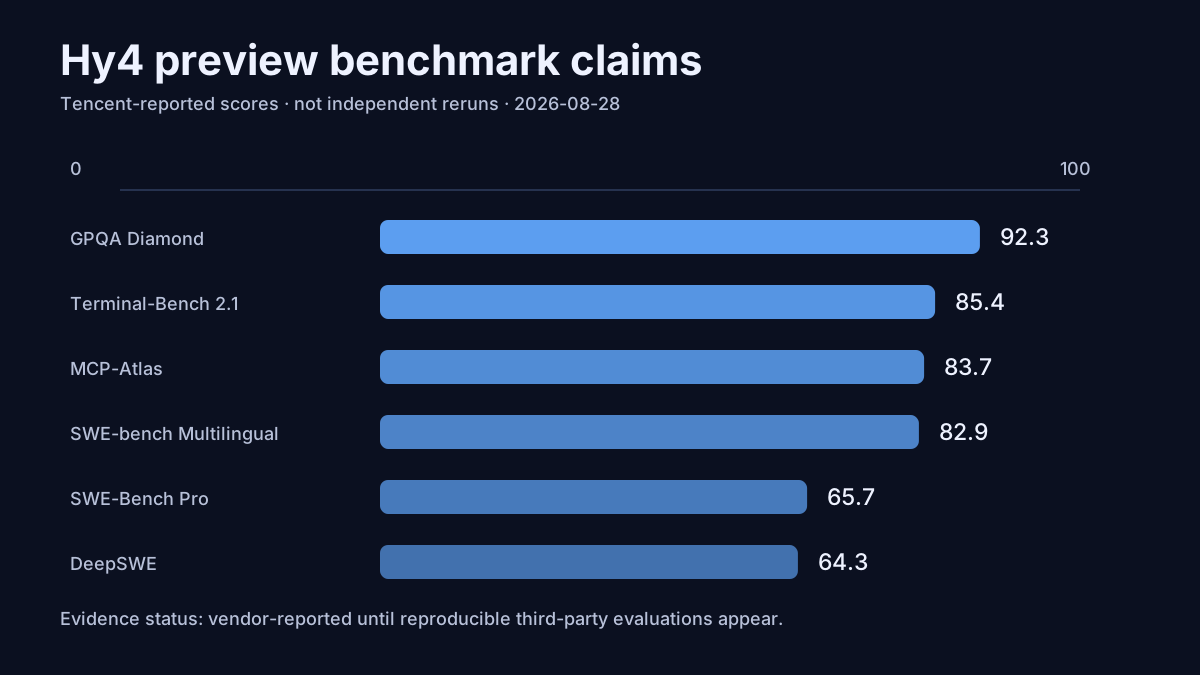
“Vendor-reported” is not a synonym for false. It is an evidence label. Agentic scores can move with the harness, tools, budget, model settings and benchmark version. Terminal-Bench 2.1 itself revised tasks that had drift or environment problems, illustrating why version and setup matter. 8
Tencent’s 163-expert blind test
Tencent also ran a blind internal comparison: 163 internal experts rated outputs on 203 engineering tasks. Hy4 preview averaged 2.99/4, versus 2.92 for GLM 5.3 and 2.94 for Kimi K3. Against GLM 5.3 Tencent reports 46.8% wins, 12.8% ties and 40.4% losses; against Kimi K3, 51.2% wins, 7.9% ties and 40.9% losses. 2
The appropriate interpretation is a narrow lead in Tencent’s internal workload, not a decisive universal win. The raters were Tencent employees and the tasks came from Tencent productivity scenarios. That is useful real-work evidence, but not independent evidence.
Open weights, Apache 2.0 — and datacenter-scale serving
Hy4 preview is licensed under Apache 2.0. 9 The open license is developer-friendly, but the model’s size changes what “self-hosting” means.
SGLang estimates approximately 1.5 TB of BF16 weights and 760 GB for the MXFP8 checkpoint. Its hardware table discusses H200, B200, B300 and GB300 configurations and explicitly budgets KV-cache memory on top of the weights. 6
The vLLM recipe’s headline describes 16×B200 or 8×B300 with MTP, and the example serves the FP8 checkpoint with tensor parallelism. 10
In other words, Hy4 is downloadable, modifiable and deployable, but it is not a casual local model. Quantization can shrink weight storage; it does not make long-context KV memory disappear, and it may introduce its own quality/kernel trade-offs.
Known limitations are unusually concrete
Tencent lists two launch-time issues: Hy4 can reason longer than necessary on complex tasks and can over-verify its own work. The team also says this is an early version with room left in both pre-training and post-training. 2
For production agents, those weaknesses translate directly into metrics that benchmark tables often hide: task completion time, reasoning-token spend, repeated tool calls, redundant checks and cost per successful job.
Where Hy4 preview fits
As of October 9, Hy4 Preview is a credible model to benchmark, not a model to declare universally best from vendor charts. The weights and API contracts are documented, but the output limit depends on provider and snapshot. The benchmark section still reflects primarily Tencent-reported August release results, not independently reproduced measurements from this publication.
That makes it easy to recommend for controlled API evaluation. It is much harder to recommend a self-hosting project without datacenter hardware, and too early to declare it the best open model solely from the published benchmark chart.
Reproducible evaluation
A reproducible comparison should compare Hy4 preview, GLM 5.3 and Kimi K3 under one harness, with identical tools, token budgets, timeouts and tasks. Report pass rate alongside total tokens, wall-clock time, tool errors, retries, verification loops and cost per completed task. That would turn launch-day benchmark claims into evidence that can support an actual deployment decision.
Source attribution and repeatability
These are three different limits, not a single universal maximum: the current OpenRouter model listing advertises 131,072 output tokens; its older dated 20260827 snapshot and Tencent Cloud’s documented TokenHub service advertise 64,000. Confirm the serving provider and model revision before reserving a 100K-token output budget. No 1M-context workload or Apple Silicon performance test was run for this article. The cache-cost examples are calculations from published prices, not measured provider bills.
Linked source index
Footnotes
Frequently Asked Questions
What is Tencent Hy4 preview?
Tencent Hy4 preview is an open Mixture-of-Experts model with 770B total parameters and 49B active parameters per token. Tencent also describes a 1M-token context window.
How much does Tencent Hy4 preview cost per million tokens?
OpenRouter lists $0.834 for input, $2.501 for output and $0.042 for cache reads per million tokens. Tencent Cloud shows 6, 18 and 0.3 CNY for the documented Guangzhou region.
Can Hy4 preview run locally?
Yes, the weights are openly available. The serving documentation lists approximately 760 GB for MXFP8 and 1.5 TB for BF16, plus multi-GPU configurations. This is not a typical laptop deployment.
Are Hy4 benchmarks independently verified?
No. The launch scores are mostly vendor-reported results or transcriptions of the model card. A reproducible third-party evaluation with the same model, harness and budget is still missing.
How does Hy4 preview compare with Hy3 preview?
Hy3 preview is described with 295B total parameters, 21B active parameters and 256K context. Hy4 preview reaches 770B, 49B and 1M.
What API limits does Hy4 preview have?
The current OpenRouter model lists 1,048,576 context and up to 131,072 output tokens. The dated 20260827 snapshot and Tencent Cloud still list 64,000 output tokens; Tencent Cloud additionally caps input at 960K.